
Over the past two years, the legal landscape surrounding artificial intelligence has shifted dramatically as rightsholders of all kinds file lawsuits against companies developing foundational AI models. Authors, publishers, and creators have increasingly targeted major tech firms, accusing them of unauthorized data harvesting, copyright infringement, and illicit distribution practices in the race to train massive language models.
Among the prominent defendants in this wave of litigation is Meta Platforms. The tech giant has found itself on the defensive in multiple high-profile legal battles, including a class-action lawsuit filed by notable authors such as Richard Kadrey and Sarah Silverman. That particular legal challenge accused Meta of training its Llama family of models on large collections of pirated books acquired from shadow libraries, and of subsequently sharing those copyrighted files with other users on the BitTorrent network during the acquisition process.
Last summer, U.S. District Judge Vince Chhabria delivered a mixed ruling in the case, determining that the actual training of the AI models on copyrighted texts constituted fair use under copyright law. However, that decision left the secondary claims regarding BitTorrent distribution and peer-to-peer uploading as the last remaining live issues in the litigation. Earlier this year, Meta introduced a fresh legal defense to address those lingering distribution claims. In a supplemental interrogatory response filed with the court, the company argued that any uploading or seeding of pirated books that occurred while its systems were downloading torrents was "part-and-parcel" of a legitimate fair use purpose.
Meta asserted in its legal filings that BitTorrent served as a more efficient and reliable means of obtaining large datasets, and that in the case of sources like Anna’s Archive, it was the only viable way to acquire the materials in bulk. Because peer-to-peer torrent networks are designed to function by having downloaders simultaneously upload data to other network participants, Meta contended that any file sharing was simply an inherent characteristic of the BitTorrent protocol itself rather than an intentional act of distribution designed to infringe copyright.
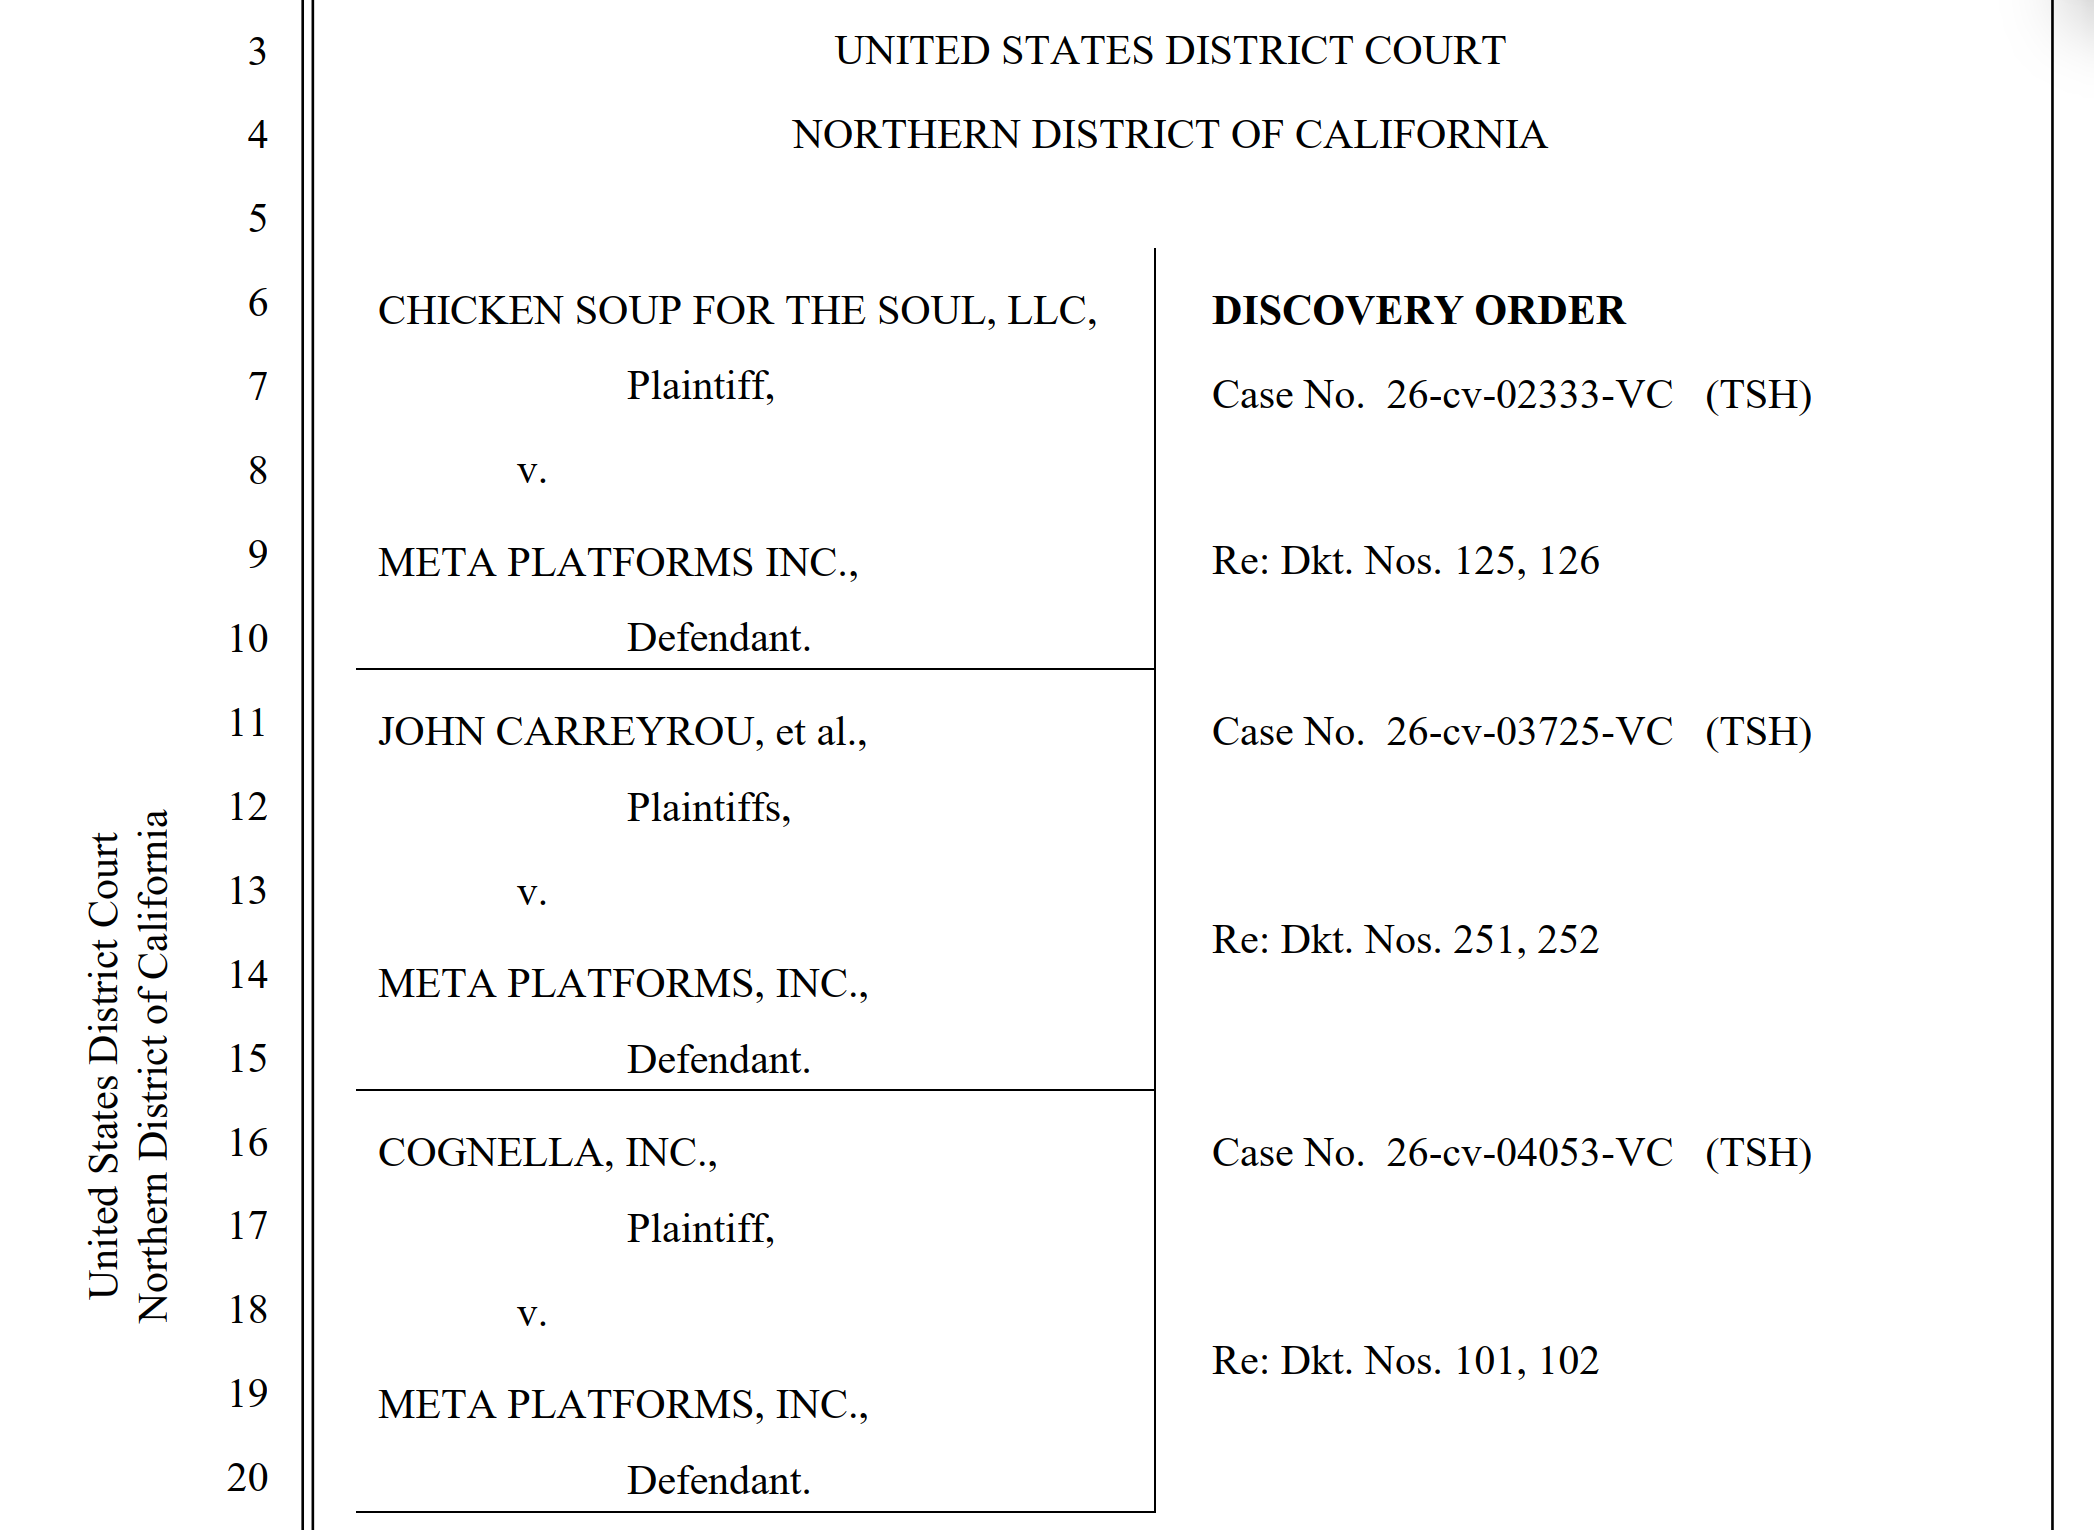
Both of Meta’s central torrenting claims are now being rigorously tested across three related lawsuits filed by Chicken Soup for the Soul, academic publisher Cognella, and John Carreyrou’s Cambronne Inc. All three of these coordinated cases have been assigned to Judge Chhabria and target the exact same shadow library torrenting activity that underpinned the earlier disputes.
Asking Torrenting AI Rivals for Evidence
Rather than waiting for Meta to fully document the technical details of its internal torrent client setup and operational procedures, the publishing plaintiffs sought to look elsewhere for answers. They decided to approach two of Meta’s primary artificial intelligence rivals, OpenAI and Anthropic, hoping to gather technical evidence that could potentially disprove Meta’s argument that seeding is an unavoidable requirement of the peer-to-peer protocol.
In August, the publishers issued formal subpoenas to both OpenAI and Anthropic. The subpoenas demanded the identity, specific software versions, and detailed configurations of every torrent client the two rival companies had utilized since 2019. Furthermore, the requests specifically sought any internal records or documentation detailing efforts made by OpenAI and Anthropic to prevent seeding or uploading while downloading training data.
In the context of similar copyright lawsuits, both OpenAI and Anthropic have previously acknowledged that they utilized books sourced from shadow libraries during the development of their own models. The reasoning behind the subpoenas was straightforward: if OpenAI and Anthropic had successfully configured their torrent clients to suppress uploading while downloading the exact same datasets, Meta’s core argument regarding the technical necessity of seeding would face severe legal jeopardy.
"If OpenAI torrented but configured its clients to suppress uploading, then the redistribution Meta calls an ‘inherent characteristic’ of the protocol was a setting Meta declined to change," the publishers argued in court documents. This line of reasoning built heavily upon an earlier discovery revelation in the litigation, which uncovered that a Meta engineer had previously written a script specifically designed to prevent seeding, though it apparently left leeching functionality intact.
OpenAI and Anthropic Push Back Against Subpoenas
Rather than complying with the broad demands for technical documentation, OpenAI and Anthropic pushed back against the subpoenas, offering significant resistance in court. Both artificial intelligence firms informed the presiding magistrate judge that examining the technical features and operational parameters of the relevant torrent client software directly would be a far more appropriate approach. They also maintained that their own internal corporate practices and software configurations had no bearing whatsoever on how Meta operated its systems.
Lawyers representing Anthropic argued vigorously against the relevance of their client’s technical setup in a filing submitted to the court. "Clients are not interchangeable, they differ in their default upload settings, in whether those defaults can be reconfigured, and in their capacity to suppress uploading during and after a download," Anthropic’s legal team wrote, emphasizing that what Anthropic’s client allowed or prohibited demonstrated nothing about the capabilities or actions of Meta’s systems.
OpenAI echoed these exact sentiments in its own legal pushback, pointing out to the court that there was no evidentiary basis to suggest that OpenAI had utilized the exact same torrent clients or built comparable corpora of data to those compiled by Meta.
Judge Sides With AI Rivals on Subpoenas
The dispute ultimately landed before Magistrate Judge Thomas Hixson, who issued a new order siding with OpenAI and Anthropic. Without ruling directly on the merits of Meta’s broader fair use and seeding arguments, the court concluded that probing the private torrent logs and internal configurations of competing AI developers was not the correct or most effective avenue for gathering evidence in the case.
"To the extent Meta’s fair use defense hinges on the assertion that its use of BitTorrent was the only way BitTorrent can be used, that assertion can be tested by examining the BitTorrent client itself," Judge Hixson wrote in his order. The court reasoned that asking third-party rivals like OpenAI or Anthropic for their historical logs would yield very little reliable insight into Meta’s specific technical setup or the generalized capabilities of the torrent software involved.
The magistrate judge further noted that any general user of a torrent client could theoretically be relevant under such a broad standard of discovery, questioning why the plaintiffs could not simply rely on their own technical experts to demonstrate how torrent clients can be utilized through direct examination of the software. Additionally, the court pointed out that the publishers’ claim that shadow library data could only be downloaded in bulk through torrent protocols was a matter that the plaintiffs could investigate by communicating directly with the libraries themselves, rather than attempting to extract derivative operational data through competing AI corporations.
Meta’s Own Server Data Remains Fair Game
While the court firmly decided that obtaining internal data and logs from Meta’s industry rivals was off-limits, a fundamentally different standard was applied to data originating directly from Meta’s own corporate servers and operational environments.
On September 11, Judge Hixson granted a significant discovery motion in the related class-action lawsuit brought forward by Richard Kadrey and other authors. This specific court order mandated the production of command history files for every server that Meta utilized during its torrenting operations, encompassing both its internal virtual machines and cloud-based Amazon Web Services instances.
Command histories function as detailed system logs that record every individual command typed or executed by an operator on a server. In the context of a machine dedicated to torrenting, these historical logs presumably reveal precise details regarding how the torrent client software was installed, configured, and operated, including any administrative changes made to upload speeds, bandwidth caps, or seeding restrictions.
This ruling traces back to earlier in the year when Meta admitted to the court that it had withheld relevant discovery documents until after the formal discovery deadlines had already elapsed. To remedy the procedural lapse and ensure fairness, Judge Chhabria granted the plaintiffs extended discovery privileges, specifically covering records that demonstrate how Meta’s torrent clients were configured and deployed in practice.
Although Meta argued that the log files it had already voluntarily turned over to the plaintiffs were more than sufficient, Judge Hixson strongly disagreed with that assessment and formally ordered the company to hand over the comprehensive command histories as well. The publishing plaintiffs and authors hope that these newly accessible command histories will finally provide definitive proof regarding which specific copyrighted works Meta acquired via torrent protocols.
Whether the server logs will ultimately provide clear answers remains to be seen as the litigation moves forward. For the time being, the central question of whether Meta could have successfully downloaded the contested books without engaging in peer-to-peer seeding has been placed squarely in the hands of the plaintiffs’ technical experts. Those experts will rely heavily on Meta’s own internal server records as they prepare their opening expert reports, which are scheduled to be submitted later this month.
Leave a Reply