
Inside modern data centres, the Transmission Control Protocol (TCP) has quietly evolved into one of the most computationally expensive operations performed by a Central Processing Unit (CPU). While network hardware has scaled impressively over recent years while maintaining reasonable power footprints—such as single NVIDIA ConnectX-7 Network Interface Controllers handling 400Gbps and 300 million packets per second at roughly 25 watts—software network stacks have failed to keep pace. Consequently, these software layers have transformed into dominant bottlenecks, preventing infrastructure operators from translating raw hardware advancements into tangible application performance.
Even when utilizing the most advanced kernel-bypass network stacks, communication-intensive applications frequently burn up to 74% of their available CPU cycles within the transport layer rather than executing actual application logic. As link speeds steadily climb into the terabit regime, this escalating "CPU tax" compounds into severe consequences, including dozens of wasted CPU cores, hundreds of watts of burned power, stranded network bandwidth, and heavily inflated tail latencies.
For years, data centre operators have been forced to live with an uncomfortable design compromise. Traditional software-implemented TCP remains exceptionally flexible, highly interoperable, and robust, but it must execute on general-purpose CPUs. Conversely, hardware-implemented transports—such as Remote Direct Memory Access (RDMA) and specialized TCP offload engines—offer blistering speed and efficiency, but they are notoriously rigid and brittle to operate at cloud scale.
RDMA serves as a textbook example of this dilemma. Originally engineered for tightly controlled, lossless fabrics at a significantly smaller scale, its retrofit into massive, multi-tenant data centre networks has proven error-prone and notoriously slow. Progress is heavily gated by lengthy hardware iteration cycles. Furthermore, a transport mechanism permanently etched into silicon denies network operators the ability to dynamically debug, trace, manage, and rapidly adapt the network stack to meet emerging application requirements or changing deployment needs. Because of these operational hurdles, hardware transports remain largely confined to specialized silos like high-performance computing clusters and dedicated storage networks, leaving software stacks as the default choice everywhere else.
A collaborative research initiative between the University of Washington and the Max Planck Institute for Software Systems (MPI-SWS), developed by researchers Rajath Shashidhara, Antoine Kaufmann, and Simon Peter, aims to break this long-standing tension. Named Presto, the project is built upon the Reconfigurable Match-action Table (RMT) architecture. This foundational design underpins modern programmable network switches like the Intel Tofino series, as well as an expanding ecosystem of SmartNICs, including AMD’s Pensando data processing units.
The RMT architecture is uniquely capable of sustaining deterministic, line-rate packet processing at rates reaching billions of packets per second. It delivers sub-microsecond latency alongside Application-Specific Integrated Circuit (ASIC)-class power efficiency, while remaining fully software programmable through the Programming Protocol-Independent Packet Processors (P4) language.
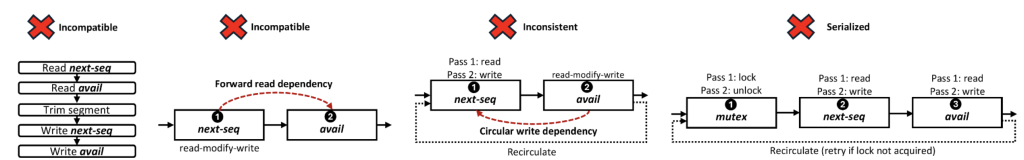
However, translating TCP’s complex state machine into a format suitable for RMT presents a fundamental architectural challenge, as TCP is historically ill-suited to RMT’s strictly unidirectional execution model. Presto successfully resolves this fundamental mismatch by implementing a complete TCP stack expressed entirely through match-action operations. This approach unlocks true ASIC performance and power efficiency while preserving the critical agility and flexibility inherent to software-defined systems.
Challenges for TCP on RMT
To understand the core engineering hurdle, one must examine how the RMT architecture processes network traffic. When a packet arrives, the system parses it into a header vector, then pushes that vector through a fixed, linear sequence of match-action stages. Each stage performs simple Arithmetic Logic Unit operations against stage-local memory in absolute lock-step. Every single packet traverses the exact same physical path in the exact same number of clock cycles, and each stage is restricted to a fixed, highly constrained budget of match-action logic.
While this strict architectural rigidity is the primary source of RMT’s deterministic behavior and energy efficiency, it is simultaneously the root cause of its extreme programming difficulty. TCP, by its very nature, requires complex, highly interdependent state updates. Vital parameters such as congestion window boundaries, sequence numbers, and out-of-order packet bookkeeping must frequently be updated multiple times and in arbitrary sequences based on incoming acknowledgments and network conditions.
An RMT pipeline, however, permits none of these traditional behaviors natively. Within an RMT pipeline, state is strictly stage-local, packets can only ever move forward through the pipeline stages, and packets are entirely prohibited from revisiting earlier stages to update historical states. Direct, naive implementations of TCP on RMT hardware have historically fallen into severe architectural traps.
Reconciling TCP state with RMT constraints
To overcome these severe architectural limitations, Presto introduces a series of dedicated design techniques that directly address each constraint imposed by the RMT model. Rather than forcing complex, multi-pass logic into a single hardware pass, Presto reorganizes transport processing so that state dependencies are cleanly decoupled and mapped efficiently onto the available match-action stages.

The detailed mechanics of these specific design principles, as applied comprehensively to the TCP state machine, were formally detailed by the research team in a paper presented at the ACM SIGCOMM conference. By systematically decoupling dependent variables and distributing state tracking across the linear pipeline without violating forward-only packet movement, Presto achieves what was previously thought to be virtually impossible for stateful transport protocols on programmable hardware.
A modular data-path, and why that matters
Unlike legacy, fixed-function hardware offloads that offer zero customization once manufactured, Presto features a data-path that is fully programmable from end to end. To make this high degree of programmability computationally and architecturally tractable, the RMT data path executes core transport logic—including window management, packet reassembly, acknowledgment generation, sequence-to-address translation for Direct Memory Access (DMA), and advanced rate control—not as a monolithic block, but as a sequence of decoupled, independently programmable functional blocks. Each of these functional blocks spans several match-action stages within the pipeline.
This deliberate modularity provides profound operational advantages. It allows infrastructure operators to evolve transport semantics, rapidly modify congestion-control algorithms, or seamlessly integrate application-level co-designs by simply editing a concise set of P4 code lines, completely bypassing the need to redesign underlying silicon hardware pipelines.
Presto redefines the software TCP design space
The research team built a fully functional prototype of Presto utilizing an Intel Tofino 2 switch hosted on a Netberg Aurora 810 hardware platform, and subsequently conducted rigorous performance comparisons against standard Linux network stacks, the TCP Acceleration Service (TAS) kernel-bypass stack, and conventional RDMA deployments.
The results demonstrate that Presto successfully dissolves the historical trade-off between high performance, hardware efficiency, and software flexibility. By combining the POSIX sockets interface of standard TCP with the raw processing speed and energy characteristics of custom ASICs, Presto achieves terabit-scale throughput and microsecond-level tail latencies while slashing CPU utilization and power consumption.
Conclusion
Ultimately, Presto enables network operators to retain the exact transport protocols they already deploy and deeply understand—standard TCP paired with a familiar POSIX sockets interface—requiring zero modifications to existing enterprise applications. Because the underlying data path is fully programmable in P4, transport logic can evolve on a rapid software release cycle rather than being chained to a vendor’s protracted silicon manufacturing cycle.
More broadly, the Presto project fundamentally redefines the design space for high-performance TCP stacks by conclusively demonstrating that full-featured transport functionality can fit comfortably within strict RMT hardware constraints. While initially rooted in TCP, the foundational principles established by Shashidhara, Kaufmann, and Peter extend far beyond a single protocol. Any reliable transport protocol shares identical structural requirements—tracking in-flight data, recovering efficiently from packet loss, and regulating transmission rates. Mapping stateful protocols onto programmable hardware under rigid timing and resource budgets represents a universal challenge for modern programmable data planes.
The complete Presto framework has been released as open source software, built for the Intel Tofino 2 and validated on Netberg Aurora 810 hardware equipped with ConnectX Network Interface Controllers. The public repository includes an extensive experimentation framework covering Remote Procedure Call scalability, packet-loss resilience, incast traffic management, performance isolation, key-value stores, shared logs, and NVMe-over-Fabrics benchmarks.
Because unmodified legacy applications run seamlessly over its POSIX sockets abstraction layer, organizations can deploy existing enterprise software—such as memcached, Nginx, and SPDK—directly on top of Presto without recompiling their source code. Operating natively via standard TCP, the stack can run concurrently alongside existing legacy infrastructure to facilitate direct, side-by-side performance comparisons in production environments.
Leave a Reply