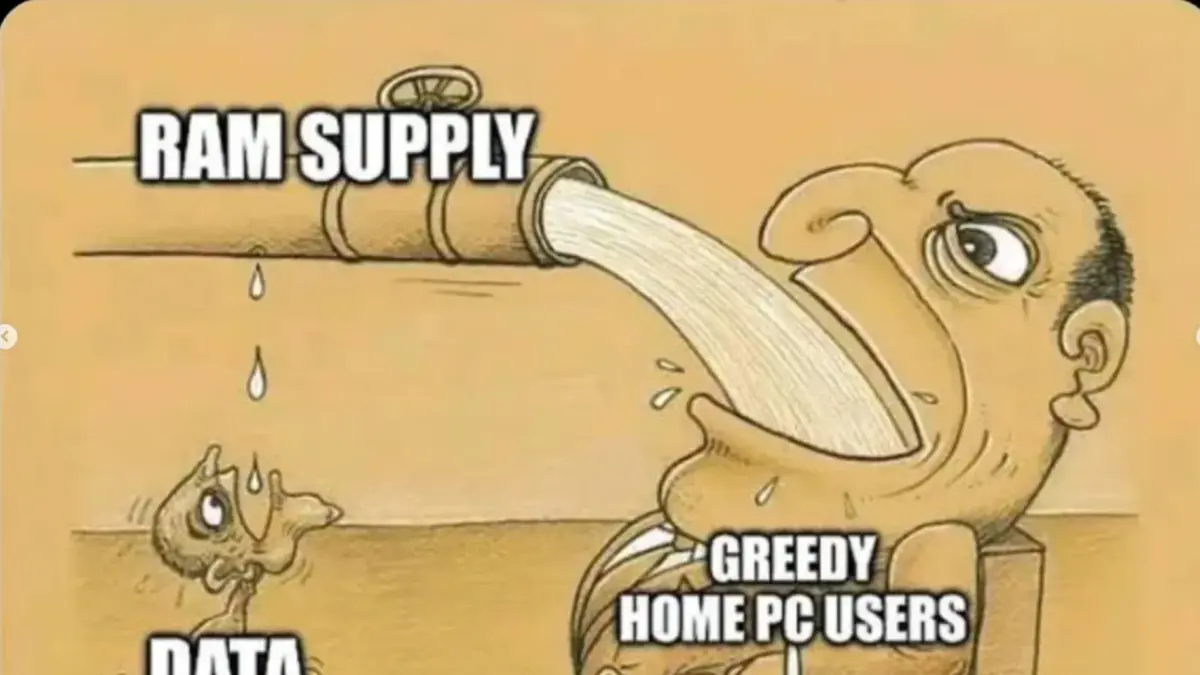
OpenAI CEO Sam Altman recently sparked a lively debate across the tech community by describing it as "quite terrible" that a vast portion of the world’s limited DRAM capacity sits idle inside personal computers for roughly 95 percent of the time. In his perspective, that memory would perform far more intensive work if concentrated inside massive cloud data centers.
For everyday computer owners and open-source advocates, however, idle RAM is not a waste—it is the very price of digital autonomy. Having spare memory means owning your hardware outright, ensuring that no corporation can rent it out from under you, alter its pricing overnight, or switch it off remotely. That foundational sense of ownership underpins the entire ethos of personal computing and user privacy.
Beyond the philosophical debate over personal hardware, recent developments in the open-source ecosystem, the Linux kernel, and Big Tech financial disclosures highlight a rapidly shifting landscape where local computing, AI integration, and infrastructure demands collide.
AI in the Kernel
The release of Linux 7.4-rc1 brought major headlines to the open-source community, driven by what Linus Torvalds confirmed was the largest merge window in the history of the kernel. The development cycle saw an overwhelming 19,671 commits, a significant leap from the 16,267 commits recorded during the 7.3 cycle.
Torvalds largely credited this unprecedented volume of activity to a wave of bug fixes discovered and flagged by artificial intelligence tools. Rather than dealing with lingering vulnerabilities as late-stage patches during the release candidate phase, developers caught and addressed these issues early in the merge window, a dynamic Torvalds described as a notably healthier model for kernel maintenance.
While AI tools played a prominent role in streamlining bug discovery, other factors also contributed to the record-breaking size of the update. Linux 7.4 is anticipated to serve as the next long-term support (LTS) kernel, naturally attracting higher contributor activity. Additionally, a substantial portion of the patch—roughly a third—consisted of AMD GPU register headers, reflecting ongoing hardware enablement across the ecosystem.
Big Tech Watch
Sam Altman’s fixation on the world’s distributed personal RAM makes sense when viewed against the backdrop of staggering financial realities within the technology sector. Recent reports from Nikkei Asia indicate that off-balance-sheet AI obligations across industry giants such as Alphabet, Microsoft, Amazon, Meta, and Oracle surged by 90 percent over a six-month period, reaching an estimated $3.2 trillion.
These figures represent a mountain of signed data center leases that have not yet become operational, alongside massive outstanding orders for specialized chips and high-performance servers. If these immense financial commitments were fully integrated into standard balance sheets immediately, the resulting market pressure could heavily impact share prices.

Trillions of dollars worth of newly constructed and planned data centers require immense resources to operate at capacity—including a nearly insatiable demand for memory. That underlying corporate pressure explains why leaders of major AI labs are increasingly eyeing the untapped memory pools sitting quietly on desks around the world.
The Open Source Response and Local AI Tools
While centralizing infrastructure remains a priority for corporate AI providers, the local Linux and open-source ecosystems continue to offer compelling alternatives for users who prefer keeping their data and hardware processing entirely under their own roof.
Recent software releases underscore this momentum. Superwhisper, a popular macOS dictation application designed for system-wide voice input, recently expanded its footprint by launching a native Linux application. The tool allows users to choose between local transcription running entirely on their own CPU or GPU, or cloud-based processing for maximum speed. However, it remains proprietary, closed-source software.
For users committed strictly to open-source alternatives, projects like voiceio provide a powerful MIT-licensed offline dictation option. Operating seamlessly across both Wayland and X11 display servers, voiceio streams transcribed text directly into whichever active application the user has open. Furthermore, the application can fine-tune its underlying speech model using local audio recordings while the computer is idle, automatically switching to the newly optimized model only if it demonstrates superior accuracy scores.
Infrastructure security for self-hosted environments has also advanced. OpenKruise Agents, a tool designed for running AI agent sandboxes within a private Kubernetes cluster, introduces architectural safeguards to prevent unauthorized data exposure. The system utilizes an egress proxy that pulls necessary API keys directly from Kubernetes Secrets and appends them to requests only as they leave the sandbox. By combining this mechanism with strict Layer 4 and Layer 7 egress rules alongside an allowlist for Model Context Protocol tools, the framework ensures that a prompt-injected AI agent cannot wander into sensitive internal networks. While such robust configurations may exceed the needs of a standard laptop, they offer valuable architecture for teams managing self-hosted AI deployments.
Understanding AI Jargon: The KV Cache
As local AI experimentation grows more common, understanding the technical terminology behind large language models becomes increasingly important. When a model generates text, it retains specific working data for every individual token processed within a conversation, eliminating the need to recalculate context from scratch. This stored operational memory is known as the KV, or key-value, cache.
The memory footprint of the KV cache expands dynamically as the conversation context length increases. This growth explains why a model that operates smoothly during a brief chat can suddenly run out of available memory the moment a user pastes an extensive document into the prompt window, highlighting the ongoing tension between hardware resource limits and expanding AI capabilities.