
The legal battlefields surrounding artificial intelligence training practices continue to expand, pulling major tech companies into complex disputes over copyright infringement, fair use doctrines, and technical methods of data acquisition. In the latest development of an ongoing copyright lawsuit against Meta Platforms, a federal magistrate judge has ruled that rival artificial intelligence developers OpenAI and Anthropic do not have to hand over their proprietary torrent logs and configuration files to plaintiffs. The decision marks a notable procedural victory for the competing AI firms, keeping their internal technical operations shielded from the broader discovery process involving Meta.
Over the past two years, copyright holders, publishers, authors, and creators of all kinds have initiated a wave of lawsuits against companies that develop large language models and other artificial intelligence systems. These legal challenges primarily focus on the foundational phase of model development, specifically targeting the vast datasets used to train models like Meta’s Llama series. Plaintiffs argue that ingesting copyrighted books, articles, and other creative works without authorization or compensation constitutes widespread infringement.
Meta finds itself embedded in a lengthy roster of technology corporations facing these legal headwinds. Among the most prominent actions is a class-action lawsuit originally filed by authors including Richard Kadrey and Sarah Silverman. That complaint accused Meta of training its Llama models on pirated books sourced from unauthorized repositories, alleging that the company actively shared those copyrighted files with other users via the BitTorrent network during the acquisition process.
The BitTorrent Defense and Fair Use
The legal landscape of the case shifted significantly last summer when U.S. District Judge Vince Chhabria issued a ruling concluding that the actual AI model training process itself constituted fair use under copyright law. While that decision handed Meta a substantial victory, it left the BitTorrent distribution claims as the final remaining live battleground in the litigation.
Earlier this year, Meta introduced a novel line of defense to address those lingering allegations regarding peer-to-peer file sharing. In a supplemental interrogatory response submitted to the court, Meta argued that any uploading of pirated books that occurred while its systems downloaded files via BitTorrent was an unavoidable, "part-and-parcel" element of carrying out a fair use purpose.
Meta elaborated on this stance by asserting that BitTorrent represented a more efficient and reliable mechanism for obtaining massive datasets compared to traditional channels, and in the specific case of the shadow library known as Anna’s Archive, it served as the only viable method to acquire the data in bulk. Because the underlying architecture of the BitTorrent protocol requires users to upload data to others while they download, Meta contended that any incidental sharing was simply an inherent characteristic of the protocol itself rather than an intentional act of redistribution.
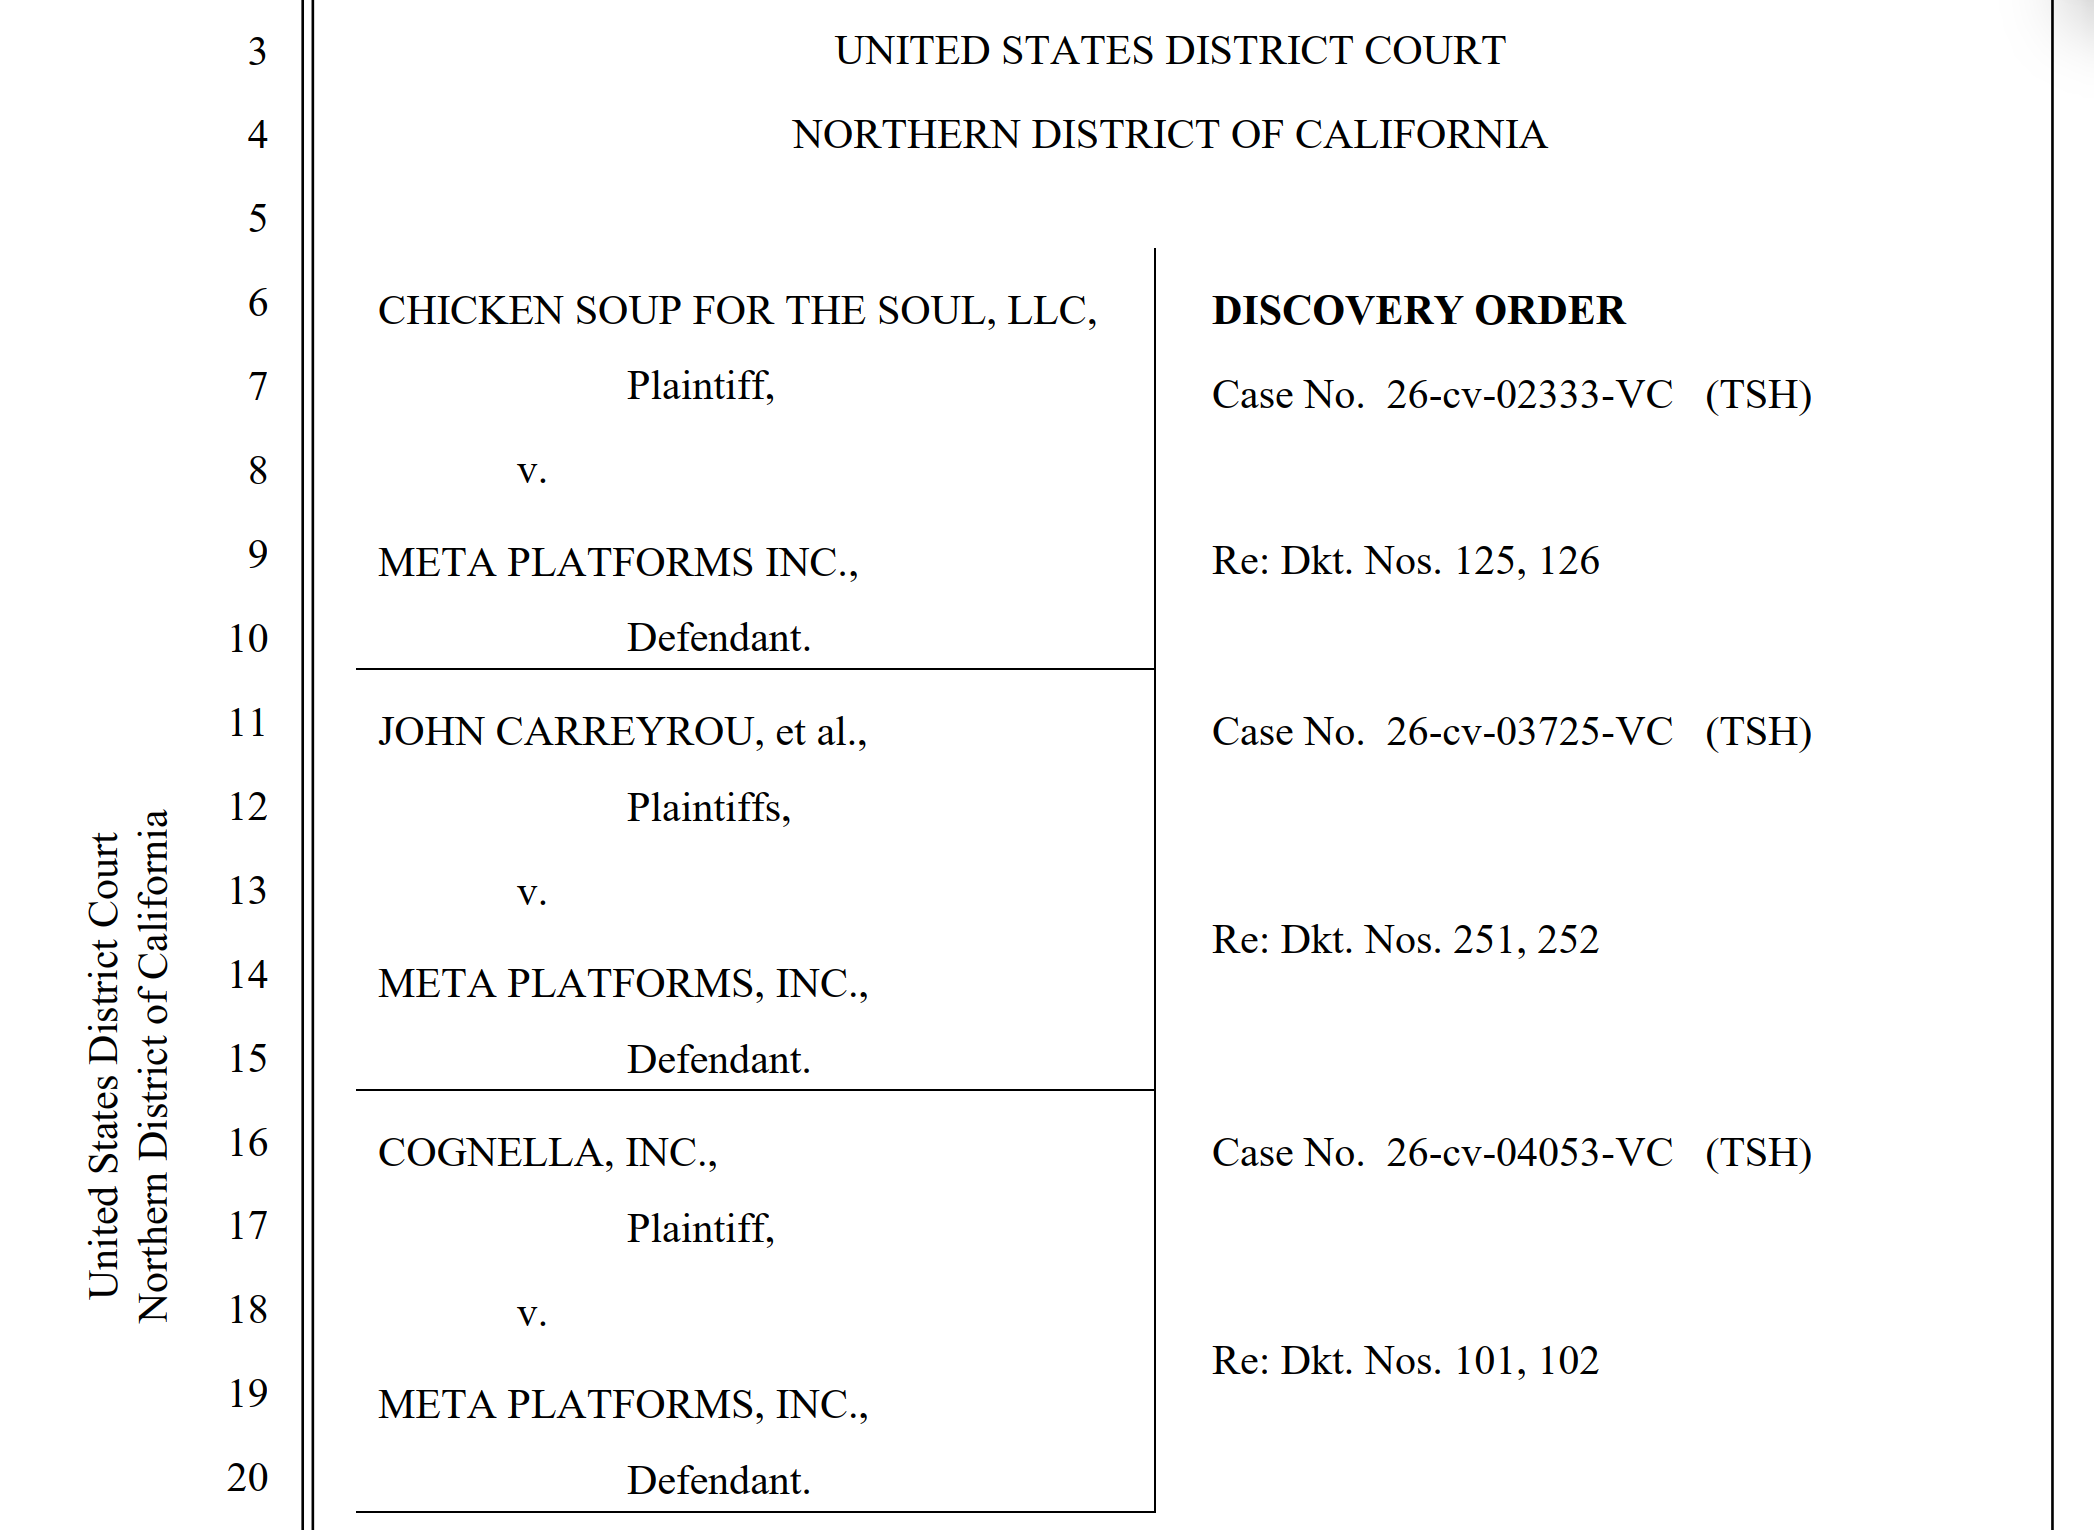
Meta’s torrenting claims are currently being tested across three closely related lawsuits filed by Chicken Soup for the Soul, academic publisher Cognella, and John Carreyrou’s Cambronne Inc. All three of these coordinated cases have been assigned to Judge Chhabria and target the same underlying shadow library torrenting activity.
Publishers Ask Torrenting AI Rivals for Records
Rather than waiting for Meta to fully document the technical intricacies of its specific torrent client setup and network configurations, the publishing plaintiffs decided to seek evidence from alternative industry sources. They targeted two of Meta’s primary artificial intelligence rivals, hoping to uncover data that could potentially disprove Meta’s assertion that uploading is an unavoidable requirement of the BitTorrent protocol.
In August, the publishers issued formal subpoenas to both OpenAI and Anthropic. The subpoenas demanded the identity, specific software versions, and configuration histories of every torrent client the companies had utilized since 2019. Furthermore, the requests specifically targeted any internal records concerning efforts by OpenAI or Anthropic to prevent seeding—the process by which files are uploaded to other peers on the network.
In the context of similar copyright lawsuits, both OpenAI and Anthropic have previously acknowledged utilizing books sourced from shadow libraries to train their own models. The plaintiffs reasoned that if these rival corporations successfully configured their torrent clients to block uploading while downloading training data, Meta’s core argument regarding the absolute necessity of seeding would crumble.
In court filings, the publishers argued that if OpenAI engaged in torrenting but actively configured its clients to suppress uploading, then the redistribution that Meta characterized as an inherent characteristic of the protocol was actually nothing more than a software setting that Meta simply chose not to change. This line of argument built directly upon an earlier evidentiary finding in the legal proceedings, which revealed that a Meta engineer had previously written a script designed to prevent seeding, though it reportedly did not block leeching.
OpenAI and Anthropic Push Back Against Subpoenas
Rather than complying with the broad document demands, OpenAI and Anthropic pushed back aggressively against the subpoenas. Instead of handing over extensive technical logs, the companies informed the court that examining the technical features of the specific torrent client used by Meta would be a far more direct and appropriate path of inquiry. Furthermore, they argued that their own internal corporate practices and software configurations had no bearing on what Meta did or did not do.
Legal representatives for Anthropic emphasized the distinct nature of peer-to-peer software in their filings, noting that torrent clients are not interchangeable. They pointed out that different clients vary widely in their default upload settings, in whether those default configurations can be modified by the operator, and in their technical capacity to suppress uploading during and after a download. Anthropic’s lawyers argued that whatever Anthropic’s chosen client permitted or restricted demonstrated nothing about the capabilities or actions of Meta’s setup.
OpenAI echoed these sentiments in its own opposition papers, highlighting the complete lack of evidentiary support connecting OpenAI’s torrenting practices to Meta’s operations. OpenAI noted that there was no proof to suggest it had utilized the same torrent clients or built comparable corpora of data to those assembled by Meta.
Magistrate Judge Sides With AI Rivals
Following briefing on the matter, U.S. Magistrate Judge Thomas Hixson issued an order siding squarely with OpenAI and Anthropic. Without making any final determination on the underlying merits of Meta’s seeding arguments, the court concluded that the torrent logs and internal records of competing AI developers were simply not the appropriate or most reliable place for the plaintiffs to gather evidence.
In the written order, Judge Hixson noted that to the extent Meta’s fair use defense hinges on the assertion that its use of BitTorrent reflected the only possible way the protocol can be operated, that specific assertion can be effectively tested by examining the BitTorrent client software itself and consulting qualified experts.
The court reasoned that asking third-party competitors like OpenAI or Anthropic for their historical logs provides virtually no insight into Meta’s specific technical infrastructure or the general technical capabilities of the software. Judge Hixson questioned the logic of the subpoenas, noting that virtually any user of a torrent client could be considered relevant under the plaintiffs’ broad standard, and asked why the plaintiffs’ own technical experts could not simply use the torrent clients directly to demonstrate how the software functions.
Additionally, the court addressed the publishers’ claim that shadow library data could only be acquired in bulk through torrent networks, pointing out that such factual assertions could be verified by communicating directly with the shadow libraries themselves rather than dragging rival AI companies into burdensome discovery disputes.
Meta’s Own Server Data Remains Fair Game
While the court drew a firm boundary protecting competing AI developers from third-party subpoenas, a different standard applies to evidence originating directly from Meta’s own corporate servers and operational infrastructure.
In a separate ruling issued in September, Judge Hixson granted a motion filed by the plaintiffs in the class-action lawsuit led by Richard Kadrey and other authors. That specific judicial order mandated the production of command history files for every server that Meta utilized during its torrenting operations, encompassing both internal virtual machines and cloud-hosted Amazon Web Services instances.
Command histories function as detailed server logs that record every command typed or executed by an operator. In the context of machines dedicated to torrenting datasets, these logs are expected to reveal critical operational details, including precisely how the torrent client software was installed, configured, and whether any modifications were made to its default upload settings over time.
This discovery dispute traces back to early 2025, when Meta disclosed that it had withheld relevant technical documents until after the formal discovery deadline had already passed. To remedy the late disclosure, Judge Chhabria granted the authors supplementary discovery opportunities, specifically targeting records that illuminate how Meta’s torrenting clients were established and operated.
Although Meta argued that the log files and documentation it had already provided to the plaintiffs were fully sufficient, Judge Hixson disagreed with that assessment and formally ordered the company to turn over the requested command histories.
The plaintiffs anticipate that these command histories will also shed light on precisely which copyrighted works Meta downloaded via torrent networks. Whether the server records will definitively answer those questions remains to be seen as the litigation moves forward.
For the time being, the central question of whether Meta could have successfully downloaded the contested books without simultaneously seeding them to the network falls to the plaintiffs’ expert witnesses, who will analyze Meta’s server records. Opening expert reports in the Meta cases are scheduled to be submitted later this month.
Leave a Reply